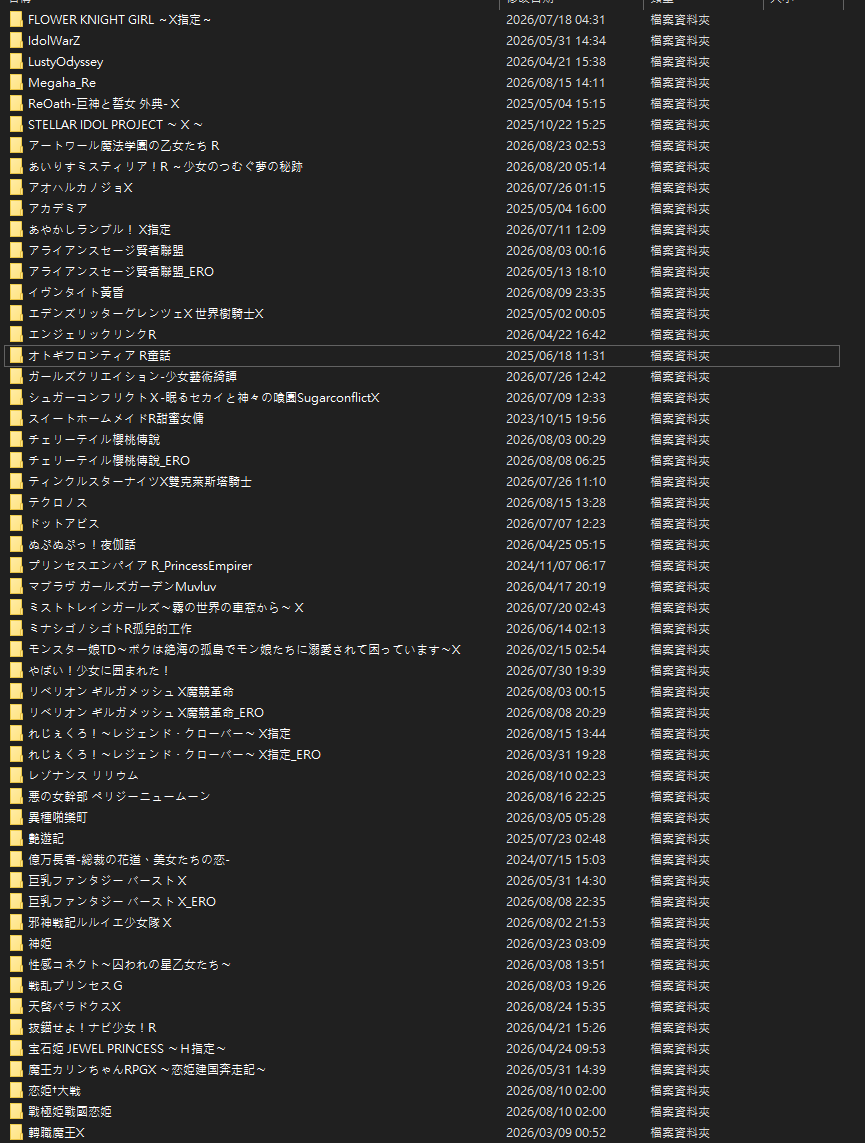
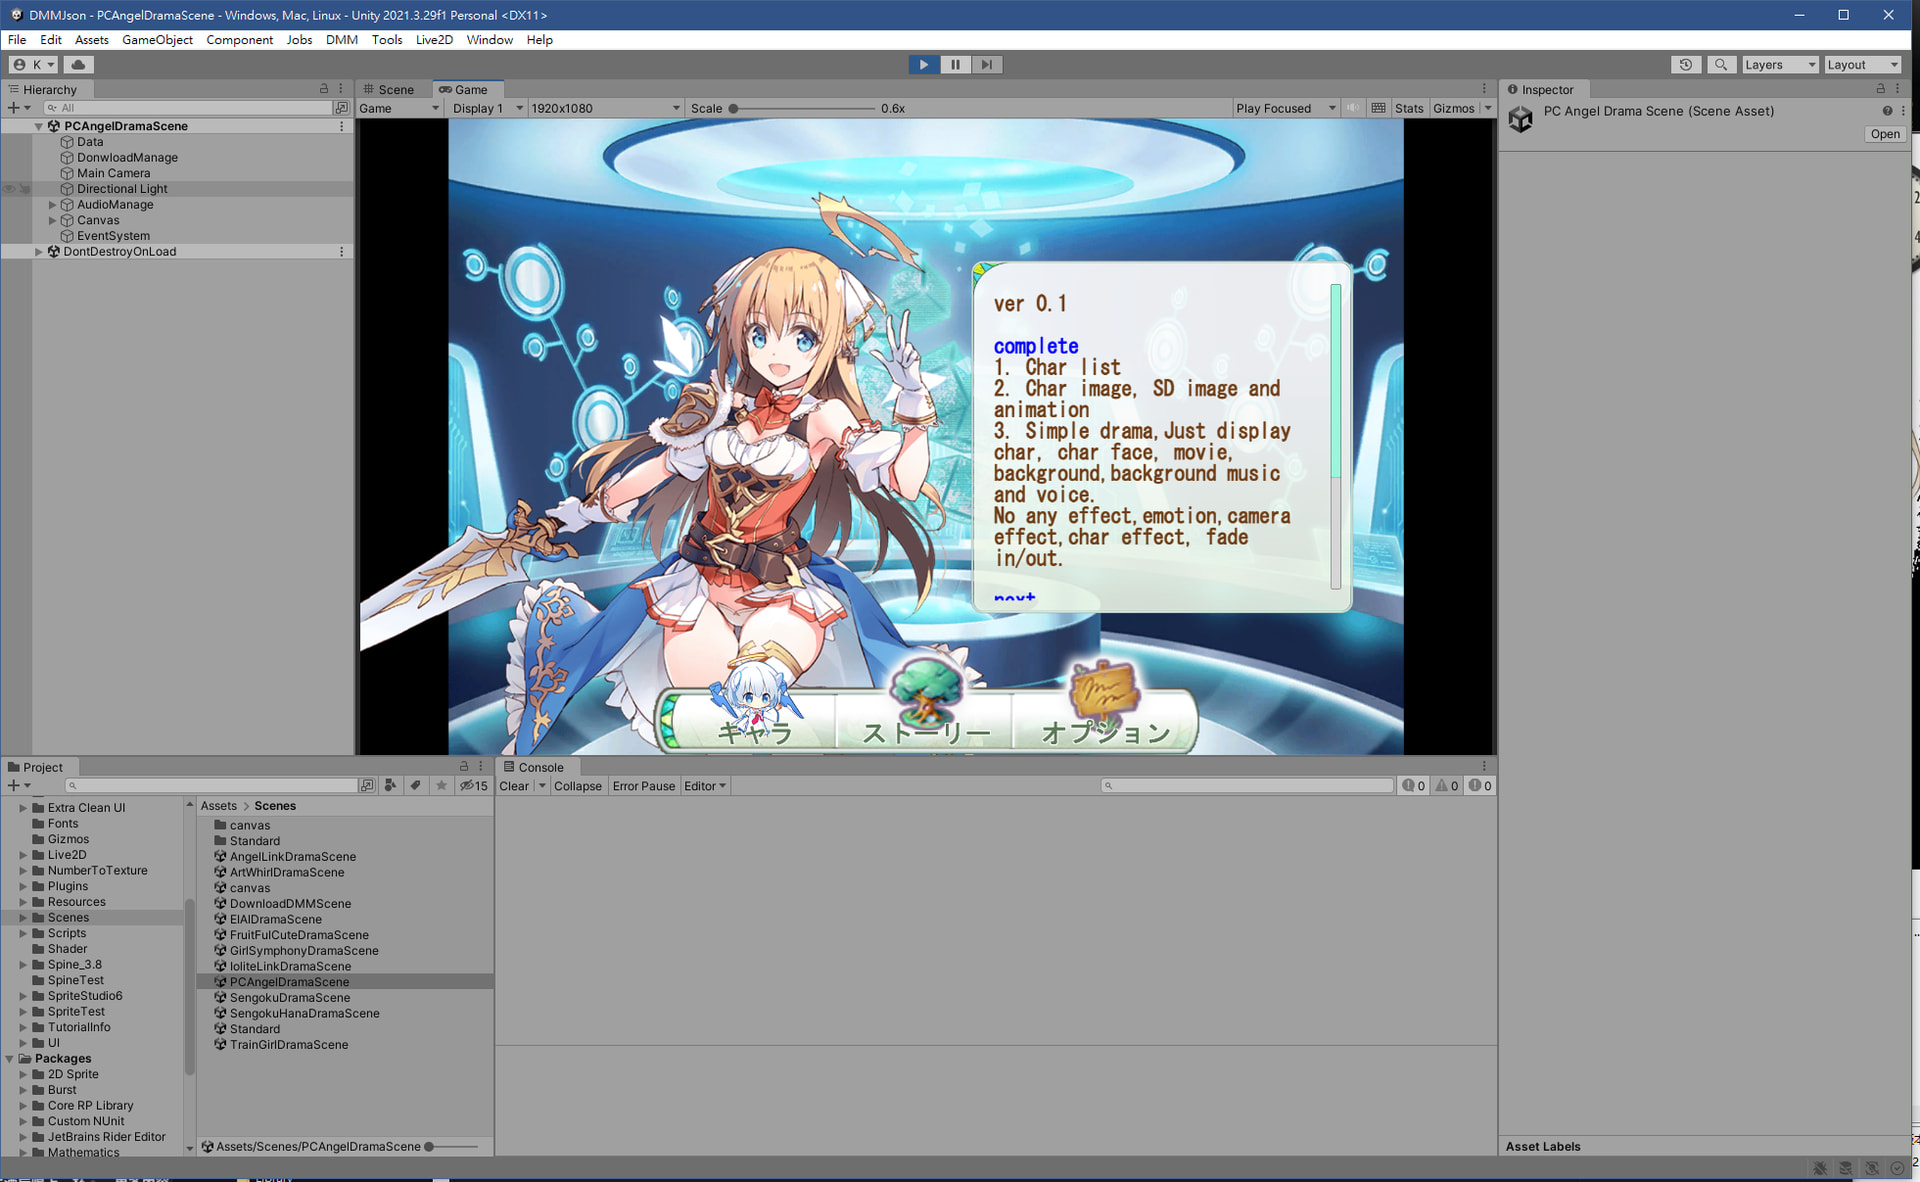
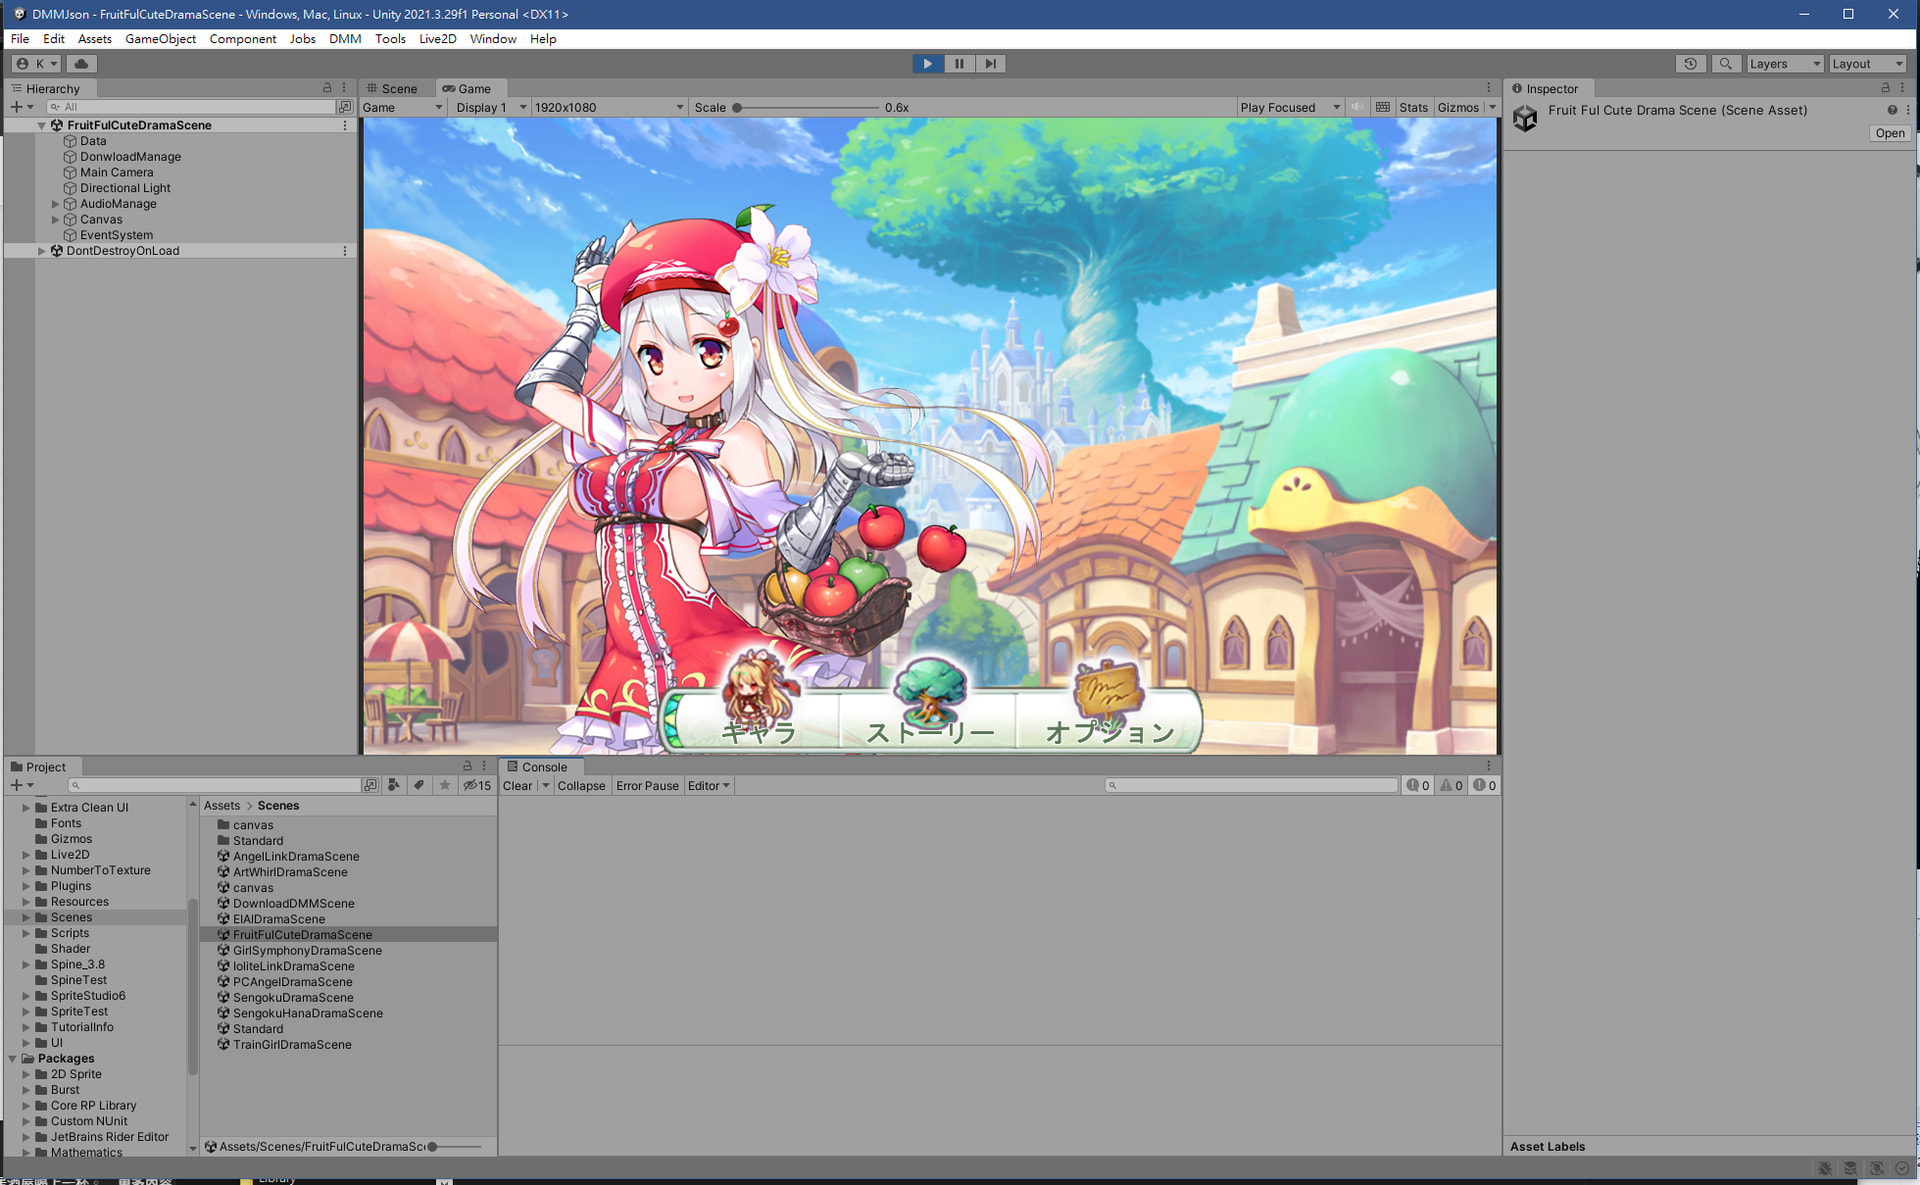
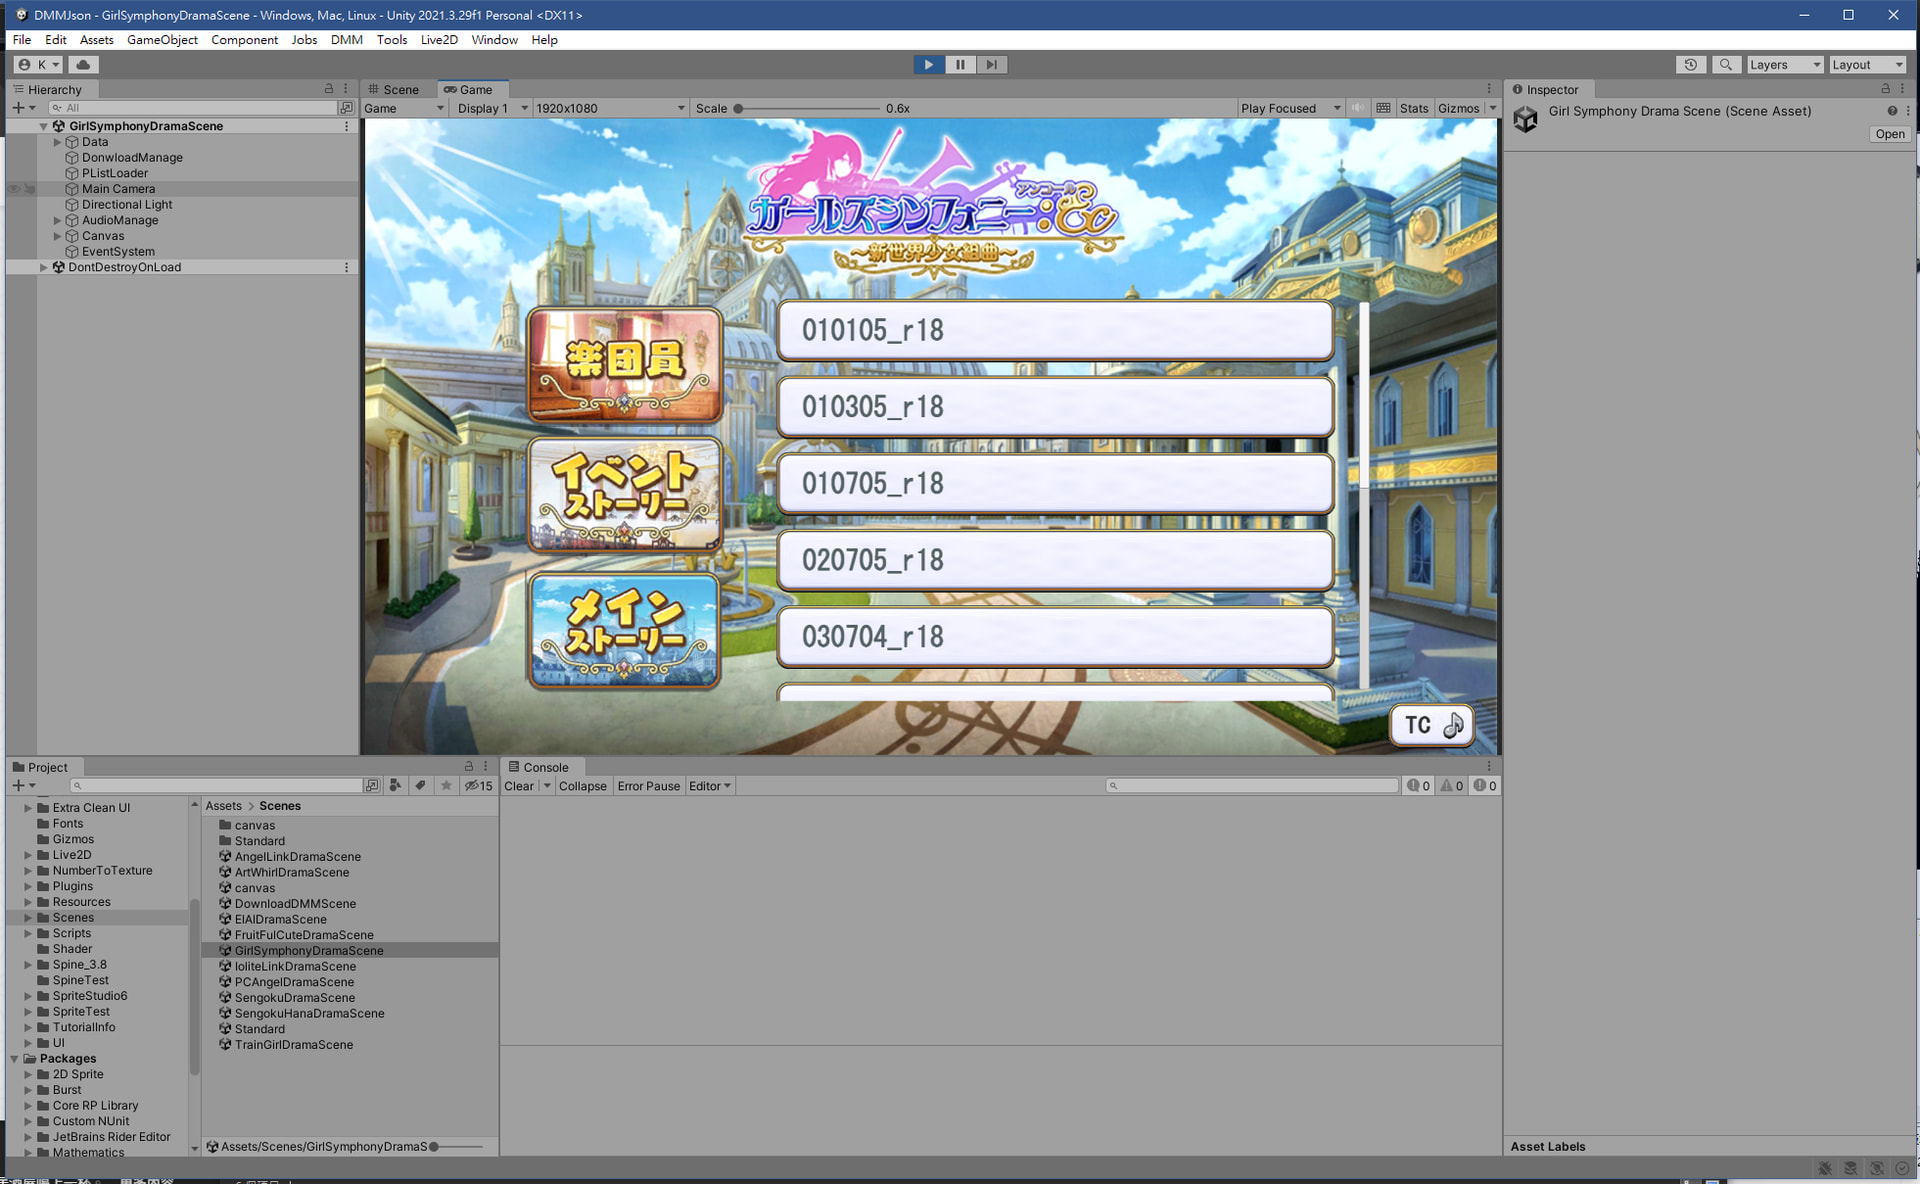
各位大佬们,请问天启悖论角色寝室数据怎么拉取,这个游戏是能拉全量寝室数据还是只能供档,供档的话也麻烦大佬们给个方法,我这里有账号,谢谢
拼接样例
不知道全不全
你看看这个资产下载脚本,剧本我也没找到
import os
import re
import json
import time
import argparse
import threading
from pathlib import Path
from typing import Any, List, Set, Tuple, Dict
from urllib.parse import urlparse, unquote, quote

import requests
import urllib3
from concurrent.futures import ThreadPoolExecutor, as_completed

urllib3.disable_warnings(urllib3.exceptions.InsecureRequestWarning)

# =========================
# Part 1: Configuration
# =========================
API_URL = "https://app-paripari-prod.tenkei-paradox.com/api/Environment/EnvConfiguration"
CDN_PREFIX = "https://cdne-paripari-prod.tenkei-paradox.com/production/"

SCRIPT_DIR = os.path.dirname(os.path.abspath(__file__))
DOWNLOAD_DIR = os.path.join(SCRIPT_DIR, '天啓パラドクスX资产')
CATALOG_DIR = os.path.join(SCRIPT_DIR, '天啓パラドクスX配置')
RECORD_FILE = os.path.join(SCRIPT_DIR, '天啓パラドクスX下载记录.json')
URLS_FILE = os.path.join(SCRIPT_DIR, '天啓パラドクスX下载链接.txt')
FAILED_URLS_FILE = os.path.join(SCRIPT_DIR, '天啓パラドクスX下载失败链接.json')
VERSION_FILE = os.path.join(SCRIPT_DIR, '天啓パラドクスX版本信息.json')

MAX_THREADS = 8
SAVE_INTERVAL = 2
CHUNK_SIZE = 1024 * 1024
AUTO_START = True

RED = '\033[91m'
GREEN = '\033[92m'
YELLOW = '\033[93m'
RESET = '\033[0m'

record_lock = threading.Lock()

CATALOG_FILES = [
    'base_catalog.json',
    'vfx_catalog.json',
    'assets_catalog.json',
    '3dModels_catalog.json',
    'pp_sounds_catalog.json',
    'pp_ui_catalog.json',
    'pp_sounds_data1_catalog.json',
    'pp_assets_data1_catalog.json',
    'pp_sounds_data2_catalog.json',
]


# =========================
# Part 2: API & Version Management
# =========================
def get_latest_version_info() -> Dict[str, Any] | None:
    """
    从 EnvConfiguration API 获取最新版本信息。
    返回包含 version_id, base_url, assets_url 的字典。
    """
    headers = {
        'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36',
        'Accept': '*/*',
        'Accept-Encoding': 'gzip, deflate, br',
        'Connection': 'keep-alive'
    }

    try:
        print(f"  正在获取云端版本信息: {API_URL}")
        resp = requests.get(API_URL, headers=headers, timeout=30, verify=False)
        if resp.status_code != 200:
            print(f"  {RED}API请求失败: {resp.status_code}{RESET}")
            return None

        data = resp.json()
        assets_url = data.get('result', {}).get('assetsUrl', '')
        if not assets_url:
            print(f"  {RED}API响应中缺少 assetsUrl{RESET}")
            return None

        version_match = re.search(r'production/(production\d+-[a-f0-9-]+)/', assets_url)
        if not version_match:
            print(f"  {RED}无法从 assetsUrl 解析版本号{RESET}")
            return None

        version_id = version_match.group(1)
        base_url = f"{CDN_PREFIX}{version_id}/"

        return {
            'version_id': version_id,
            'base_url': base_url,
            'assets_url': assets_url,
            'api_response': data
        }
    except Exception as e:
        print(f"  {RED}获取版本信息错误: {e}{RESET}")
        return None


def load_version_record() -> Dict[str, Any]:
    """加载本地版本记录文件。"""
    if os.path.exists(VERSION_FILE):
        with open(VERSION_FILE, 'r', encoding='utf-8') as f:
            return json.load(f)
    return {
        'last_version_id': '',
        'last_check_time': '',
        'version_history': []
    }


def save_version_record(record: Dict[str, Any]):
    """保存版本记录到文件。"""
    with open(VERSION_FILE, 'w', encoding='utf-8') as f:
        json.dump(record, f, ensure_ascii=False, indent=2)


def compare_versions(old_version: str, new_version: str) -> Tuple[str, bool]:
    """
    对比两个版本号,返回状态描述和是否需要更新。
    """
    if not old_version:
        return "首次运行", True

    if old_version == new_version:
        return "版本相同", False

    old_num = re.search(r'production(\d+)', old_version)
    new_num = re.search(r'production(\d+)', new_version)

    if old_num and new_num:
        old_n = int(old_num.group(1))
        new_n = int(new_num.group(1))
        if new_n > old_n:
            return f"版本升级: {old_n} -> {new_n}", True
        elif new_n < old_n:
            return f"版本降级: {old_n} -> {new_n} (异常)", True

    return f"版本变更: {old_version} -> {new_version}", True


# =========================
# Part 3: Catalog Management
# =========================
def get_catalog_urls(base_url: str) -> Dict[str, str]:
    """生成所有 catalog 文件的 URL 映射。"""
    return {
        'settings.json': base_url + 'WebGL/StreamingAssets/aa/settings.json',
        'catalog.json': base_url + 'WebGL/StreamingAssets/aa/catalog.json',
        'base_catalog.json': base_url + 'Assets/WebGL/base_catalog.json',
        'vfx_catalog.json': base_url + 'Assets/WebGL/vfx_catalog.json',
        'assets_catalog.json': base_url + 'Assets/WebGL/assets_catalog.json',
        '3dModels_catalog.json': base_url + 'Assets/WebGL/3dModels_catalog.json',
        'pp_sounds_catalog.json': base_url + 'Assets/WebGL/pp_sounds_catalog.json',
        'pp_ui_catalog.json': base_url + 'Assets/WebGL/pp_ui_catalog.json',
        'pp_sounds_data1_catalog.json': base_url + 'Assets/WebGL/pp_sounds_data1_catalog.json',
        'pp_assets_data1_catalog.json': base_url + 'Assets/WebGL/pp_assets_data1_catalog.json',
        'pp_sounds_data2_catalog.json': base_url + 'Assets/WebGL/pp_sounds_data2_catalog.json',
    }


def download_catalogs(base_url: str, force_update: bool = False) -> Tuple[List[str], List[str]]:
    """
    下载 catalog 文件到配置文件夹。
    返回 (已下载列表, 已跳过列表)。
    """
    os.makedirs(CATALOG_DIR, exist_ok=True)

    headers = {
        'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36',
        'Accept': '*/*',
        'Accept-Encoding': 'gzip, deflate, br',
        'Connection': 'keep-alive'
    }

    session = requests.Session()
    catalog_urls = get_catalog_urls(base_url)

    downloaded = []
    skipped = []

    for name, url in catalog_urls.items():
        save_path = os.path.join(CATALOG_DIR, name)

        if not force_update and os.path.exists(save_path):
            skipped.append(name)
            continue

        try:
            resp = session.get(url, headers=headers, timeout=30, verify=False)
            if resp.status_code == 200:
                with open(save_path, 'w', encoding='utf-8') as f:
                    f.write(resp.text)
                downloaded.append(name)
            else:
                print(f"    {RED}{name}: HTTP {resp.status_code}{RESET}")
        except Exception as e:
            print(f"    {RED}{name}: {e}{RESET}")

    return downloaded, skipped


def parse_catalogs() -> List[str]:
    """解析所有 catalog 文件(从配置文件夹),提取 bundle 名称列表。"""
    bundles = set()
    bundle_pattern = r'"([^"]*\.bundle)"'

    for catalog_file in CATALOG_FILES:
        filepath = os.path.join(CATALOG_DIR, catalog_file)
        if not os.path.exists(filepath):
            continue

        with open(filepath, 'r', encoding='utf-8') as f:
            content = f.read()

        found = re.findall(bundle_pattern, content)
        for bundle in found:
            bundles.add(bundle)

    return list(bundles)


# =========================
# Part 4: Bundle Path Conversion
# =========================
def convert_bundle_path(bundle_path: str) -> str:
    """将 bundle 名称转换为完整的下载路径。"""
    if bundle_path.startswith('PariPariPublicRemote/'):
        return 'Assets/WebGL/' + bundle_path[len('PariPariPublicRemote/'):]
    elif bundle_path.startswith('PariPariRemote/'):
        return 'Assets/WebGL/' + bundle_path[len('PariPariRemote/'):]
    elif bundle_path.startswith('{UnityEngine.AddressableAssets.Addressables.RuntimePath}/'):
        return 'WebGL/StreamingAssets/aa/' + bundle_path[len('{UnityEngine.AddressableAssets.Addressables.RuntimePath}/'):]
    elif bundle_path.startswith('Assets/'):
        return bundle_path
    else:
        return 'Assets/WebGL/' + bundle_path


def safe_filename(s: str) -> str:
    """将字符串转换为安全的文件名。"""
    return re.sub(r'[^A-Za-z0-9._-]+', "_", s)


# =========================
# Part 5: Download Record Management
# =========================
def load_record() -> Dict[str, Any]:
    """加载下载记录文件。"""
    if os.path.exists(RECORD_FILE):
        with open(RECORD_FILE, 'r', encoding='utf-8') as f:
            return json.load(f)
    return {
        'last_update': '',
        'current_version': '',
        'total_count': 0,
        'downloaded_bundles': [],
        'bundle_hashes': {}
    }


def save_record(record: Dict[str, Any]):
    """保存下载记录到文件。"""
    with record_lock:
        with open(RECORD_FILE, 'w', encoding='utf-8') as f:
            json.dump(record, f, ensure_ascii=False, indent=2)


def get_local_bundles() -> Set[str]:
    """扫描本地目录,获取已存在的 bundle 文件集合。"""
    local = set()
    if os.path.exists(DOWNLOAD_DIR):
        for root, dirs, files in os.walk(DOWNLOAD_DIR):
            for file in files:
                if file.endswith('.bundle'):
                    local.add(file)
    return local


# =========================
# Part 6: Download Functions
# =========================
def download_stream(url: str, out_path: str, timeout: int = 60, retries: int = 3) -> Tuple[bool, int, int]:
    """
    流式下载文件,支持重试。
    返回 (成功, 状态码, 字节数)。
    """
    headers = {"User-Agent": "Mozilla/5.0", "Accept": "*/*"}

    for attempt in range(1, retries + 1):
        try:
            with requests.get(url, stream=True, timeout=timeout, headers=headers, verify=False) as r:
                sc = r.status_code
                if sc != 200:
                    return False, sc, 0

                tmp = out_path + ".part"
                total = 0
                with open(tmp, "wb") as f:
                    for chunk in r.iter_content(CHUNK_SIZE):
                        if chunk:
                            f.write(chunk)
                            total += len(chunk)
                os.replace(tmp, out_path)
            return True, 200, total
        except Exception as e:
            if attempt == retries:
                print(f"{RED}[FAIL]{RESET} {url} -> {e}")
                return False, -1, 0
            time.sleep(0.8 * attempt)
    return False, -1, 0


def download_file(bundle_name: str, base_url: str, session: requests.Session, headers: Dict[str, str]) -> Tuple[bool, str, int, int]:
    """
    下载单个 bundle 文件。
    返回 (成功, bundle名, 状态码/错误, 大小)。
    """
    converted_path = convert_bundle_path(bundle_name)
    encoded_path = quote(converted_path, safe='/')
    url = base_url + encoded_path
    save_path = os.path.join(DOWNLOAD_DIR, os.path.basename(bundle_name))

    try:
        resp = session.get(url, headers=headers, timeout=60, verify=False)
        if resp.status_code == 200:
            with open(save_path, 'wb') as f:
                f.write(resp.content)
            return True, bundle_name, 200, len(resp.content)
        return False, bundle_name, resp.status_code, 0
    except Exception as e:
        return False, bundle_name, str(e), 0


def draw_progress_bar(progress: float, completed: int, total: int, remaining_time: float):
    """绘制进度条。"""
    bar_length = 50
    filled_length = int(bar_length * progress)

    if progress < 0.3:
        color = RED
    elif progress < 0.7:
        color = YELLOW
    else:
        color = GREEN

    bar = f"{color}{'█' * filled_length}{RESET}{'-' * (bar_length - filled_length)}"

    hours = int(remaining_time // 3600)
    minutes = int((remaining_time % 3600) // 60)
    seconds = int(remaining_time % 60)

    if hours > 0:
        time_str = f"{hours}时{minutes}分{seconds}秒"
    elif minutes > 0:
        time_str = f"{minutes}分{seconds}秒"
    else:
        time_str = f"{seconds}秒"

    print(f"\r[{bar}] {completed}/{total} ({progress*100:.1f}%) 剩余: {time_str}", end='', flush=True)


def generate_urls_file(bundles: List[str], base_url: str):
    """生成下载链接文件。"""
    with open(URLS_FILE, 'w', encoding='utf-8') as f:
        f.write(f"Total: {len(bundles)}\n")
        f.write(f"Base URL: {base_url}\n\n")
        for bundle in bundles:
            converted_path = convert_bundle_path(bundle)
            url = base_url + converted_path
            f.write(f"{url}\n")
    print(f"{GREEN}[OK]{RESET} 下载链接已保存到: {GREEN}{URLS_FILE}{RESET}")


def save_failed_urls_json(failed_bundles: List[Tuple[str, str, str]], base_url: str, version_id: str = ''):
    """保存下载失败链接到 JSON 文件(实时更新)。"""
    data = {
        'total_failed': len(failed_bundles),
        'base_url': base_url,
        'version_id': version_id,
        'update_time': time.strftime('%Y-%m-%d %H:%M:%S'),
        'failed_urls': [
            {
                'bundle': bundle_name,
                'url': url,
                'error': error
            }
            for bundle_name, url, error in failed_bundles
        ]
    }
    with open(FAILED_URLS_FILE, 'w', encoding='utf-8') as f:
        json.dump(data, f, ensure_ascii=False, indent=2)


def download_bundles(new_bundles: List[str], base_url: str, bundles: List[str],
                     current_version_id: str, downloaded_bundles: Set[str],
                     record: Dict[str, Any], version_record: Dict[str, Any]) -> Tuple[int, int, int]:
    """
    执行 bundle 下载。
    返回 (成功数, 失败数, 总大小)。
    """
    headers = {
        'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36',
        'Accept': '*/*',
        'Accept-Encoding': 'gzip, deflate, br',
        'Connection': 'keep-alive'
    }

    session = requests.Session()

    completed = 0
    failed = 0
    total_size = 0
    start_time = time.time()
    last_save_time = start_time
    failed_bundles_list: List[Tuple[str, str, str]] = []

    with ThreadPoolExecutor(max_workers=MAX_THREADS) as executor:
        futures = {executor.submit(download_file, bundle, base_url, session, headers): bundle for bundle in new_bundles}

        for future in as_completed(futures):
            success, bundle_name, status, size = future.result()

            if success:
                completed += 1
                total_size += size
                downloaded_bundles.add(os.path.basename(bundle_name))
            else:
                failed += 1
                converted_path = convert_bundle_path(bundle_name)
                url = base_url + converted_path
                error_msg = f"HTTP {status}" if isinstance(status, int) else str(status)
                failed_bundles_list.append((bundle_name, url, error_msg))
                save_failed_urls_json(failed_bundles_list, base_url, current_version_id)

            current_time = time.time()
            if current_time - last_save_time >= SAVE_INTERVAL:
                record['downloaded_bundles'] = list(downloaded_bundles)
                record['total_count'] = len(bundles)
                record['current_version'] = current_version_id
                record['last_update'] = time.strftime('%Y-%m-%d %H:%M:%S')
                save_record(record)
                last_save_time = current_time

            progress = (completed + failed) / len(new_bundles)
            elapsed = current_time - start_time
            if completed > 0:
                avg_time = elapsed / completed
                remaining_time = avg_time * (len(new_bundles) - completed - failed)
            else:
                remaining_time = 0

            draw_progress_bar(progress, completed + failed, len(new_bundles), remaining_time)

    print()

    elapsed = time.time() - start_time

    record['downloaded_bundles'] = list(downloaded_bundles)
    record['total_count'] = len(bundles)
    record['current_version'] = current_version_id
    record['last_update'] = time.strftime('%Y-%m-%d %H:%M:%S')
    save_record(record)

    version_record['last_version_id'] = current_version_id
    version_record['last_check_time'] = time.strftime('%Y-%m-%d %H:%M:%S')
    existing_versions = [v.get('version_id') for v in version_record.get('version_history', [])]
    if current_version_id not in existing_versions:
        version_record.setdefault('version_history', []).append({
            'version_id': current_version_id,
            'check_time': time.strftime('%Y-%m-%d %H:%M:%S'),
            'bundle_count': len(bundles),
            'downloaded_count': completed
        })
    save_version_record(version_record)

    if failed_bundles_list:
        print(f"{RED}[FAIL]{RESET} 失败链接已实时保存到: {RED}{FAILED_URLS_FILE}{RESET}")

    print(f"\n{'=' * 60}")
    print(f"下载完成!")
    print(f"  版本: {current_version_id}")
    print(f"  成功: {GREEN}{completed}{RESET}")
    print(f"  失败: {RED}{failed}{RESET}")
    print(f"  总大小: {total_size / 1024 / 1024:.2f} MB")
    print(f"  耗时: {elapsed:.1f} 秒")
    if elapsed > 0:
        print(f"  速度: {total_size / 1024 / 1024 / elapsed:.2f} MB/s")
    print(f"{'=' * 60}")

    return completed, failed, total_size


# =========================
# Part 7: Main Pipeline
# =========================
def run_get_version() -> Tuple[str, str] | None:
    """
    获取云端版本信息。
    返回 (version_id, base_url) 或 None。
    """
    print(f"{YELLOW}[*]{RESET} GET {API_URL}")
    version_info = get_latest_version_info()

    if not version_info:
        print(f"{RED}[WARN]{RESET} 无法获取云端版本信息")
        return None

    version_id = version_info['version_id']
    base_url = version_info['base_url']

    print(f"{GREEN}[OK]{RESET} 当前云端版本: {GREEN}{version_id}{RESET}")
    print(f"{GREEN}[OK]{RESET} Base URL: {base_url}")

    return version_id, base_url


def run_download_catalogs(base_url: str, force_update: bool) -> Tuple[List[str], List[str]]:
    """
    下载 catalog 文件。
    返回 (已下载列表, 已跳过列表)。
    """
    print(f"{YELLOW}[*]{RESET} 检查 Catalog 文件...")
    downloaded, skipped = download_catalogs(base_url, force_update=force_update)

    if downloaded:
        print(f"{GREEN}[OK]{RESET} 已更新: {GREEN}{len(downloaded)}{RESET} 个 catalog 文件")
        for name in downloaded:
            print(f"    {GREEN}- {name}{RESET}")

    if skipped:
        print(f"{YELLOW}[SKIP]{RESET} 已跳过(未变更): {YELLOW}{len(skipped)}{RESET} 个")

    return downloaded, skipped


def run_parse_catalogs() -> List[str]:
    """
    解析 catalog 文件获取 bundle 列表。
    返回 bundle 名称列表。
    """
    print(f"{YELLOW}[*]{RESET} 解析 Catalog...")
    bundles = parse_catalogs()
    print(f"{GREEN}[OK]{RESET} 发现 {GREEN}{len(bundles)}{RESET} 个资源文件")
    return bundles


def run_calculate_diff(bundles: List[str], local_version_id: str, need_update: bool) -> Tuple[List[str], Set[str]]:
    """
    计算差异更新。
    返回 (待下载列表, 已有文件集合)。
    """
    print(f"{YELLOW}[*]{RESET} 加载下载记录...")
    record = load_record()
    downloaded_bundles = set(record.get('downloaded_bundles', []))
    print(f"{GREEN}[OK]{RESET} 已下载记录: {GREEN}{len(downloaded_bundles)}{RESET} 个")

    print(f"{YELLOW}[*]{RESET} 扫描本地文件...")
    local_bundles = get_local_bundles()
    print(f"{GREEN}[OK]{RESET} 本地文件: {GREEN}{len(local_bundles)}{RESET} 个")

    existing_bundles = downloaded_bundles | local_bundles
    new_bundles = [b for b in bundles if os.path.basename(b) not in existing_bundles]

    print(f"\n{YELLOW}[*]{RESET} 计算差异更新...")
    print(f"  云端总数: {GREEN}{len(bundles)}{RESET}")
    print(f"  已有文件: {GREEN}{len(existing_bundles)}{RESET}")
    print(f"  待下载: {YELLOW}{len(new_bundles)}{RESET}")

    if need_update and local_version_id:
        removed_bundles = [b for b in downloaded_bundles if b not in [os.path.basename(x) for x in bundles]]
        if removed_bundles:
            print(f"  {YELLOW}可能已移除: {len(removed_bundles)} 个旧版本文件{RESET}")

    return new_bundles, existing_bundles


def main():
    ap = argparse.ArgumentParser(description="天啓パラドクスX 资产下载器 (云端实时更新版)")
    ap.add_argument("--workdir", default=".", help="工作目录(默认当前目录)")
    ap.add_argument("--download-dir", default=None, help="下载目录(默认工作目录下的 天啓パラドクスX资产)")
    ap.add_argument("--threads", type=int, default=MAX_THREADS, help=f"下载线程数(默认 {MAX_THREADS})")
    ap.add_argument("--no-download", action="store_true", help="跳过下载(只生成 URL 文件)")
    ap.add_argument("--force-catalog", action="store_true", help="强制更新 catalog 文件")
    args = ap.parse_args()

    workdir = os.path.abspath(args.workdir)
    os.makedirs(workdir, exist_ok=True)
    os.chdir(workdir)

    if args.download_dir:
        global DOWNLOAD_DIR, CATALOG_DIR, RECORD_FILE, URLS_FILE, FAILED_URLS_FILE, VERSION_FILE
        DOWNLOAD_DIR = os.path.abspath(args.download_dir)
        CATALOG_DIR = os.path.join(workdir, '天啓パラドクスX配置')
        RECORD_FILE = os.path.join(workdir, '天啓パラドクスX下载记录.json')
        URLS_FILE = os.path.join(workdir, '天啓パラドクスX下载链接.txt')
        FAILED_URLS_FILE = os.path.join(workdir, '天啓パラドクスX下载失败链接.json')
        VERSION_FILE = os.path.join(workdir, '天啓パラドクスX版本信息.json')

    print("=" * 60)
    print(f"{GREEN}天啓パラドクスX 资产下载器 (云端实时更新版){RESET}")
    print("=" * 60)
    print(f"工作目录: {YELLOW}{workdir}{RESET}")
    print()

    print(f"{YELLOW}[Step 1/5]{RESET} 获取云端最新版本信息...")
    result = run_get_version()

    if not result:
        print(f"\n{RED}无法获取云端版本信息,尝试使用本地记录...{RESET}")
        version_record = load_version_record()
        if version_record.get('last_version_id'):
            version_id = version_record['last_version_id']
            base_url = f"{CDN_PREFIX}{version_id}/"
            result = (version_id, base_url)
        else:
            print(f"{RED}无本地版本记录,请检查网络连接{RESET}")
            return

    current_version_id, base_url = result

    print(f"\n{YELLOW}[Step 2/5]{RESET} 加载本地版本记录...")
    version_record = load_version_record()
    local_version_id = version_record.get('last_version_id', '')
    print(f"{GREEN}[OK]{RESET} 本地记录版本: {GREEN}{local_version_id or '无记录'}{RESET}")

    version_status, need_update = compare_versions(local_version_id, current_version_id)
    status_color = GREEN if need_update else YELLOW
    print(f"{GREEN}[OK]{RESET} 版本对比结果: {status_color}{version_status}{RESET}")

    force_catalog = args.force_catalog or need_update

    print(f"\n{YELLOW}[Step 3/5]{RESET} 下载 Catalog 文件...")
    run_download_catalogs(base_url, force_catalog)

    print(f"\n{YELLOW}[Step 4/5]{RESET} 解析 Catalog 并计算差异...")
    bundles = run_parse_catalogs()
    new_bundles, existing_bundles = run_calculate_diff(bundles, local_version_id, need_update)

    if not new_bundles:
        print(f"\n{GREEN}所有资源已下载完成!无需更新{RESET}")

        version_record['last_version_id'] = current_version_id
        version_record['last_check_time'] = time.strftime('%Y-%m-%d %H:%M:%S')
        existing_versions = [v.get('version_id') if isinstance(v, dict) else v for v in version_record.get('version_history', [])]
        if current_version_id not in existing_versions:
            version_record.setdefault('version_history', []).append({
                'version_id': current_version_id,
                'check_time': time.strftime('%Y-%m-%d %H:%M:%S'),
                'bundle_count': len(bundles)
            })
        save_version_record(version_record)

        record = load_record()
        record['current_version'] = current_version_id
        record['total_count'] = len(bundles)
        save_record(record)
        return

    print(f"\n{YELLOW}[Step 5/5]{RESET} 生成下载链接...")
    generate_urls_file(new_bundles, base_url)

    if args.no_download:
        print(f"\n{YELLOW}[SKIP]{RESET} 跳过下载 (--no-download 已指定)")
        print(f"{GREEN}[OK]{RESET} URL 文件已生成: {GREEN}{URLS_FILE}{RESET}")
        return

    if AUTO_START:
        print(f"\n{GREEN}自动开始下载...{RESET}")
    else:
        confirm = input(f"\n是否开始下载? (y/n): ").strip().lower()
        if confirm != 'y':
            print(f"{YELLOW}已取消下载{RESET}")
            return

    print(f"\n{GREEN}开始下载 {YELLOW}{len(new_bundles)}{RESET} 个文件...")
    print(f"  线程数: {GREEN}{args.threads}{RESET}")
    print(f"  保存到: {YELLOW}{DOWNLOAD_DIR}{RESET}")
    print()

    record = load_record()
    downloaded_bundles = set(record.get('downloaded_bundles', []))

    download_bundles(
        new_bundles, base_url, bundles,
        current_version_id, downloaded_bundles,
        record, version_record
    )

    print("\n" + "=" * 60)
    print(f"{GREEN}完成!{RESET}")
    print("=" * 60)


if __name__ == '__main__':
    main()
```粗体文本
你是要弄离线吗?
我记得剧本是鉴权的,供档简单抓取就行。
能否使用此脚本检索场景?
检索场景比较困难,如果可以检索到,我愿意提供帮助。
能供账号吗,就差剧本了,但是剧本需要权限  ,月底就关服
我明白是需要一个账号的。
问题在于,我实际上并没有角色。
我觉得在这种情况下,有个账号也没多大用处。
我正试着想想要在月底前做点什么,但一时半会儿也想不到……
大概有2k个角色剧情(只算r18大概也有800多,s和ur角色3个正常2个r18,a级以下的2个正常一个r18(看板娘没有)),spine动画倒是asset里都有了,他里面的剧场文本要单独鉴权(检测你抽到这个角没)然后给下载链接,除非能破认证不然是搞不到的
我知道需要进行身份验证。
我也知道根据稀有度不同,场景数量也不同。
这正是我想要解决的问题…
我之所以问,是因为你表示愿意提供一个账号。
如果我有一个拥有所有角色的账号,我自己就能搞定。
一共4000多个bin吧,1个人是搞不定的,那么多角色还要i求70级,有些角色还是氪金限定
请敎一下
我已经手动下载了几个角色的剧本 .bin
如何能转成完整的文字剧本呢?
我尝试了用python转但效果不太好
我正在收集 scenario.bin 文件;您愿意帮忙吗?
我也有办法解码这些场景文件。
我只懂得先播放后手动下载
效率不高
但如果你能提供解码方法
我也花时间愿意帮忙
我使用机器翻译。
为了避免误解,我也会使用英语。
如果意思正确,我们通过短信沟通好吗?
I am using machine translation.
To avoid any misunderstanding of my intentions, I also use English.
If my meaning is clear, would you be open to communicating via messages?
你想要实现的功能是将“.bin”文件作为文本文件读取,对吗?
Am I correct in understanding that you want to be able to read a “.bin file” as a text file?
我也来帮忙,你可以用这个 Python 工具下载 scenario.bin
也包含了我自己获取的 scenario.bin 文件
链接: 百度网盘 请输入提取码 提取码: wiz3
谢谢,我很乐意这样做。
但是,我无法使用百度网盘。
谷歌云盘或Mega网盘就太好了。
如果您能给我发条消息就更好了。
Google Drive 是最佳选择,因为它没有下载限制,但请您也告知我这方面的情况。
最近才發現要關服
只抽了幾天每日10抽, 而且沒有留意gacha機完結時間, 現在幾萬石只能抽一般機
另外
這是某角色寢室數據
“https://
cdne-paripari-prod.tenkei-paradox.com/master-data/production/scenes/21010340104.bin?sv=2021-10-04&se=2027-08-17T21:07:40Z&sr=b&sp=r&sig=pR1GkpEd%2B43HTVu2rajWniKGmraoX6GKgq2OXQQP4C0%3D”
最後面的sig=pR1GkpEd%2B43HTVu2rajWniKGmraoX6GKgq2OXQQP4C0%3D
有人試過破嗎?不知道是固定的?隨機的?還是每個人不一樣的?
上面的url有人試下載(請自行將"https://"和後面"cdne-paripari…"複製後合在一起來試)
我有大約只收集不到200角色寢室Bin檔(純寢室)URL, B+A+SR(1XX), 非寢室沒時間一個一個開收集Bin檔
有沒有人交換bin或URL
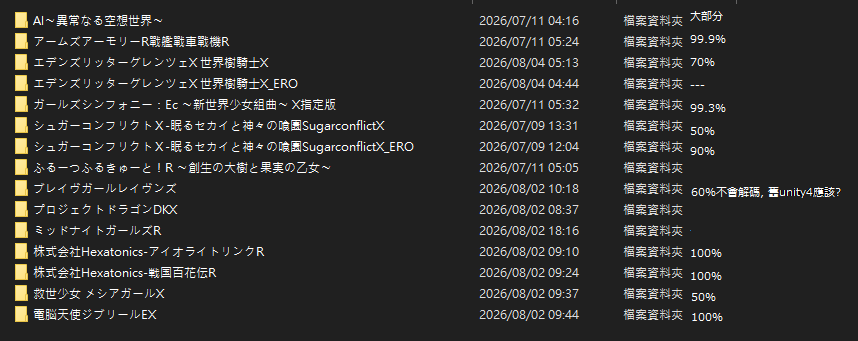
下面是我收集其他遊戲, 還有很久以前做的離線版/網頁版
2019前左右做的網頁版/離線版
因為太多遊戲, 最後停了, 只做了下面的
Unity WebGL 網頁版/Unity 離線版
エンジェリックリンクR 天使連結R 70%收集 dmm
水果很可愛 70%自己玩收集 dmm+少部分中文
交響曲少女 收集99.3%收集 dmm+少部分中文
電脳天使 100%(純寢室) dmm+少部分中文
Html5版
戦乱プリンセスG 70%自己玩收集